

Zero-downtime database migrations let you change a PostgreSQL schema while the application keeps serving traffic: no maintenance page, no failed checkouts, no queue of timed-out requests. The schema change itself is rarely the slow part. The outages come from locks: one ALTER TABLE waiting behind a long query can freeze every read on the table. This guide shows how PostgreSQL locks interact during migrations, how to guard every migration with lock_timeout, which operations are safe as written and which need a different recipe, and how to rename or retype a column with the expand-contract pattern and a batched backfill.
From my own work: The worst migration incident I have cleaned up was a one-line ALTER TABLE that added a column. The statement itself takes milliseconds, but it waited behind a reporting query that ran for minutes, and every request touching that table queued behind it. A five-second lock_timeout and a retry loop would have turned that outage into a log line.
Why migrations cause downtime: the lock queue
Most forms of ALTER TABLE need an ACCESS EXCLUSIVE lock, which conflicts with every other lock, including the ACCESS SHARE lock a plain SELECT takes (PostgreSQL: explicit locking). Locks are granted in queue order, so the sequence that causes outages looks like this:
- A long transaction or report holds
ACCESS SHAREonorders. - Your migration asks for
ACCESS EXCLUSIVEand waits. - Every new query on
ordersqueues behind the migration, even simple reads. - Connection pools fill, requests time out, and the site is down although nothing is broken.
The fix is to make migrations give up quickly instead of waiting. lock_timeout aborts a statement that waits longer than the limit for a lock, and statement_timeout caps total run time (PostgreSQL: client connection defaults):
-- at the top of every migration
SET lock_timeout = '5s';
SET statement_timeout = '15min';   -- generous for index builds, but never unlimited

-- find what is blocking right now
SELECT pid, pg_blocking_pids(pid) AS blocked_by, state,
       now() - xact_start AS xact_age, left(query, 60) AS query
FROM pg_stat_activity
WHERE cardinality(pg_blocking_pids(pid)) > 0;
A migration that fails on a lock timeout is safe to retry. Wrap the migration command in a small retry loop so a busy moment does not fail the deploy:
#!/usr/bin/env bash
# migrate-with-retry.sh: retry a migration that gave up waiting for a lock
set -uo pipefail
for attempt in 1 2 3 4 5; do
  if psql "$DATABASE_URL" -v ON_ERROR_STOP=1 -f "$1"; then
    echo "migration applied on attempt $attempt"; exit 0
  fi
  echo "attempt $attempt failed, retrying in $((attempt * 10))s" >&2
  sleep $((attempt * 10))
done
echo "migration failed after 5 attempts" >&2; exit 1
Only retry migrations that are idempotent or run in a single transaction, so a failed attempt leaves nothing half applied. Use IF NOT EXISTS where PostgreSQL supports it.
Which schema changes are safe
The table below covers the operations teams run most often, based on the ALTER TABLE and CREATE INDEX documentation (PostgreSQL: ALTER TABLE).
| Change | As written | Zero-downtime recipe |
|---|---|---|
| Add a nullable column | Brief exclusive lock, no rewrite | Safe with lock_timeout |
| Add a column with a constant default | No rewrite; the default is stored in the catalog | Safe with lock_timeout |
Add a column with a volatile default such as clock_timestamp() |
Rewrites the table and its indexes | Add nullable, backfill in batches, then set the default |
| Create an index | Blocks writes for the whole build | CREATE INDEX CONCURRENTLY |
| Add a foreign key or CHECK constraint | Scans the table while holding locks | NOT VALID, then VALIDATE CONSTRAINT |
| Set a column NOT NULL | Full scan under an exclusive lock | Validated CHECK or NOT VALID constraint first |
| Add a unique constraint | Builds the index under lock | Unique index concurrently, then USING INDEX |
| Change a column type | Usually rewrites the table | Expand-contract with a new column |
| Rename a column or table | Fast, but breaks running code | Expand-contract, or a compatibility view |
| Drop a column | Fast, but breaks code that still selects it | Remove all code references first, then drop |
Create indexes concurrently
CREATE INDEX CONCURRENTLY builds the index while inserts, updates and deletes continue. It takes longer, scans the table twice and cannot run inside a transaction block. If it fails, it leaves an invalid index behind that still costs write time, so drop it and retry (PostgreSQL: building indexes concurrently):
SET lock_timeout = '5s';
CREATE INDEX CONCURRENTLY IF NOT EXISTS orders_customer_id_idx ON orders (customer_id);

-- find invalid indexes left by a failed concurrent build
SELECT indexrelid::regclass AS index_name, indrelid::regclass AS table_name
FROM pg_index WHERE NOT indisvalid;

DROP INDEX CONCURRENTLY IF EXISTS orders_customer_id_idx;   -- then run the CREATE again

-- unique constraint without a long lock
CREATE UNIQUE INDEX CONCURRENTLY users_email_key_idx ON users (email);
ALTER TABLE users ADD CONSTRAINT users_email_key UNIQUE USING INDEX users_email_key_idx;
Check the new index with EXPLAIN before and after; a concurrent build is only worth its cost if the planner uses the result.
Foreign keys and NOT NULL without long locks
Constraints are split into two steps: add the constraint as NOT VALID, which only checks new rows and is fast, then validate it separately. Validation takes a SHARE UPDATE EXCLUSIVE lock that lets reads and writes continue.
SET lock_timeout = '5s';

-- foreign key
ALTER TABLE orders
  ADD CONSTRAINT orders_customer_id_fkey
  FOREIGN KEY (customer_id) REFERENCES customers (id) NOT VALID;
ALTER TABLE orders VALIDATE CONSTRAINT orders_customer_id_fkey;

-- NOT NULL on a large table (works on every supported version)
ALTER TABLE orders
  ADD CONSTRAINT orders_customer_id_not_null CHECK (customer_id IS NOT NULL) NOT VALID;
ALTER TABLE orders VALIDATE CONSTRAINT orders_customer_id_not_null;
ALTER TABLE orders ALTER COLUMN customer_id SET NOT NULL;   -- skips the scan: the CHECK proves it
ALTER TABLE orders DROP CONSTRAINT orders_customer_id_not_null;
The third statement is fast because PostgreSQL skips the table scan when a valid CHECK constraint already proves no NULL exists. Since PostgreSQL 18 you can also add a NOT NULL constraint itself as NOT VALID and validate it later, which avoids the temporary CHECK. Fix existing NULLs with a batched backfill before validating, or validation will fail.
Rename a column with expand-contract
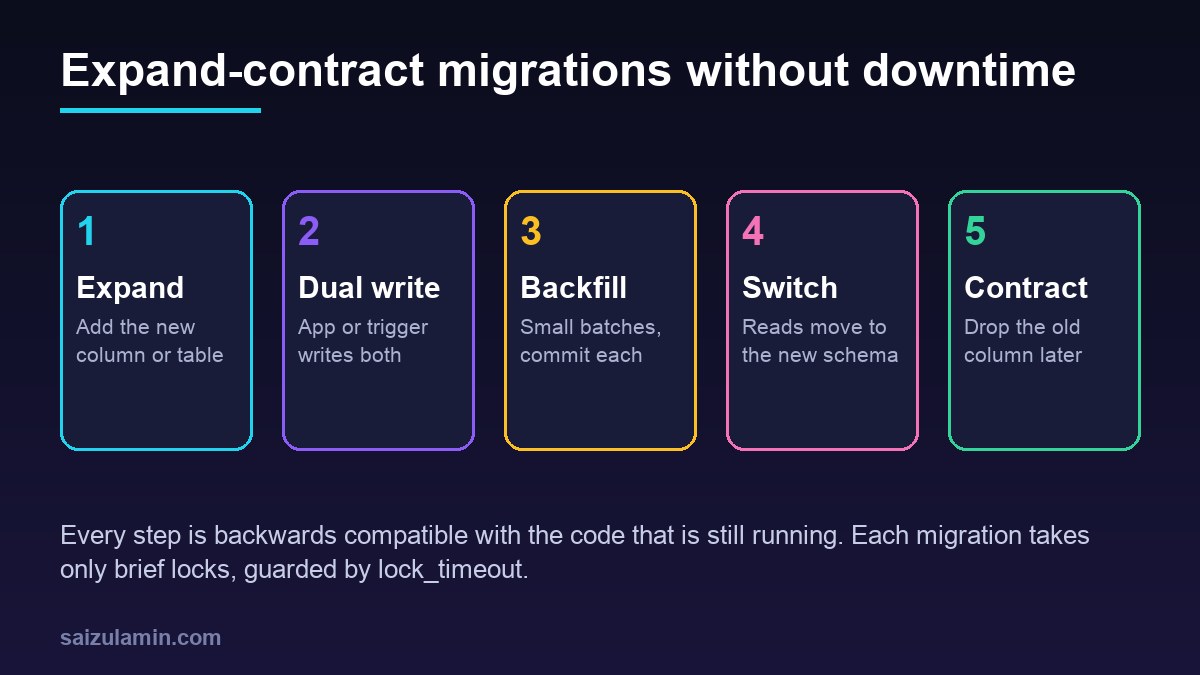
Suppose users.fullname must become users.display_name. A direct rename breaks every running instance of the old code the moment it commits. Expand-contract spreads the change over several deploys, each compatible with the version before it.
Step 1, expand: add the new column and keep it in sync while old code still writes the old one.
SET lock_timeout = '5s';
ALTER TABLE users ADD COLUMN IF NOT EXISTS display_name text;

CREATE OR REPLACE FUNCTION users_sync_display_name() RETURNS trigger
LANGUAGE plpgsql AS $$
BEGIN
  IF TG_OP = 'INSERT' THEN
    NEW.display_name := COALESCE(NEW.display_name, NEW.fullname);
  ELSIF NEW.fullname IS DISTINCT FROM OLD.fullname THEN
    NEW.display_name := NEW.fullname;            -- old code changed the old column
  ELSIF NEW.display_name IS DISTINCT FROM OLD.display_name THEN
    NEW.fullname := NEW.display_name;            -- new code changed the new column
  END IF;
  RETURN NEW;
END $$;

CREATE TRIGGER users_sync_display_name
  BEFORE INSERT OR UPDATE ON users
  FOR EACH ROW EXECUTE FUNCTION users_sync_display_name();
Step 2, backfill: copy existing rows in small batches, committing after each one so locks stay short and autovacuum can keep up. A procedure can commit inside its loop when it is called outside an explicit transaction:
CREATE OR REPLACE PROCEDURE backfill_display_name(batch_size int DEFAULT 5000)
LANGUAGE plpgsql AS $$
DECLARE
  last_id bigint := 0;
  max_id  bigint;
BEGIN
  SELECT coalesce(max(id), 0) INTO max_id FROM users;
  WHILE last_id < max_id LOOP
    UPDATE users
       SET display_name = fullname
     WHERE id > last_id AND id <= last_id + batch_size
       AND display_name IS NULL;
    last_id := last_id + batch_size;
    COMMIT;                     -- release row locks after every batch
    PERFORM pg_sleep(0.05);     -- leave room for normal traffic and replicas
  END LOOP;
END $$;

CALL backfill_display_name();   -- run outside BEGIN ... COMMIT
Transaction control in procedures is documented in the PL/pgSQL chapter (PostgreSQL: transaction management). Watch replication lag during large backfills; if replicas fall behind, increase the sleep or reduce the batch size. A logical replication setup like the one in the PostgreSQL logical replication guide is sensitive to bursts of updates in the same way.
Step 3, switch: deploy code that reads and writes display_name. The trigger keeps fullname current for any old instance still running during the rollout.
Step 4, contract: once no deployed code mentions fullname, remove the trigger and the column in a later release:
SET lock_timeout = '5s';
DROP TRIGGER IF EXISTS users_sync_display_name ON users;
DROP FUNCTION IF EXISTS users_sync_display_name();
ALTER TABLE users DROP COLUMN IF EXISTS fullname;
The same pattern changes a column type: add amount_cents bigint, sync and backfill from amount numeric, switch, then drop the old column.
Deploy order and framework settings
- Expand migrations run before the code deploy; the old code ignores new nullable columns and new indexes.
- Contract migrations run after every instance runs the new code, ideally one release later.
- Never mix both in one migration during a rolling deploy.
- Rails: use
disable_ddl_transaction!withadd_index :orders, :customer_id, algorithm: :concurrently. - Django: use
AddIndexConcurrentlyfromdjango.contrib.postgres.operationsin a migration withatomic = False. - Any tool: set
lock_timeoutfor the migration role, for exampleALTER ROLE migrator SET lock_timeout = '5s';.
Rehearse risky migrations on a copy of production first. Database branches make this cheap, as shown in the Neon database branching guide, and a restore-tested backup is the safety net for anything irreversible; see automated PostgreSQL backup verification. Application-level rollouts such as blue-green deployments only stay zero-downtime if the schema changes underneath them follow these rules.
Zero-downtime database migrations checklist
SET lock_timeoutandstatement_timeoutat the top of every migration, with retries.- No long-running transactions open when the migration starts.
- Indexes built and dropped
CONCURRENTLY; invalid indexes cleaned up. - Foreign keys and CHECK constraints added
NOT VALID, then validated. - NOT NULL set through a validated constraint.
- Renames and type changes done with expand-contract and batched backfills.
- Expand before deploy, contract one release after.
Want this done on your own server or site?
I am Saizul Amin, a web developer and technical SEO consultant. I set up and harden VPS servers, migrate WordPress sites, fix indexing problems and build automations. See my portfolio or get in touch.
FAQ
What are zero-downtime database migrations?
They are schema changes applied while the application keeps running and serving traffic. Each step takes only brief locks and stays compatible with both the old and new application code, so no maintenance window is needed.
Why does ALTER TABLE block SELECT queries in PostgreSQL?
Most ALTER TABLE forms need an ACCESS EXCLUSIVE lock. While it waits behind an existing query, new queries queue behind it, including plain SELECTs. A short lock_timeout makes the migration give up and retry instead of blocking everyone.
Can I run CREATE INDEX CONCURRENTLY in a transaction?
No. It cannot run inside a transaction block, so migration tools need a non-transactional migration for it. If the build fails, drop the invalid index it leaves behind and run it again.
How do I add NOT NULL to a large PostgreSQL table without downtime?
Add a CHECK (column IS NOT NULL) constraint as NOT VALID, validate it, then run SET NOT NULL, which skips the full scan because the valid constraint proves there are no NULLs. Finally drop the CHECK constraint.
What is the expand-contract pattern?
It splits a breaking schema change into backwards compatible steps: add the new structure, write to both old and new, backfill existing rows, switch reads, and only then remove the old structure in a later release.
Sources
- PostgreSQL Docs: ALTER TABLE
- PostgreSQL Docs: CREATE INDEX (building indexes concurrently)
- PostgreSQL Docs: Explicit locking
- PostgreSQL Docs: Client connection defaults (lock_timeout, statement_timeout)
- PostgreSQL Docs: Transaction management in PL/pgSQL

Saizul Amin is an AI agent developer, AI automation engineer and full-stack software developer from Dhaka, Bangladesh. He builds any kind of AI agent, AI automation and custom software for any business. Portfolio: https://saizul.com